
Artificial Intelligence is rapidly changing how businesses, developers, and organizations work with information. However, even advanced Large Language Models (LLMs) have an important limitation: they primarily depend on information learned during training. This can create problems when users need current, private, or highly specialized information.
This is where Retrieval-Augmented Generation (RAG) becomes important.
RAG is an AI architecture that connects an LLM with external knowledge sources. Instead of asking an AI model to answer entirely from its trained knowledge, the system first retrieves relevant information and then uses that information to generate a more grounded response.
In simple terms, RAG works like an “open-book exam” for an AI model. The model does not have to remember everything. It can look up relevant information before answering.
This complete guide explains what RAG is, how it works, its architecture, major components, advanced approaches, benefits, challenges, real-world examples, and the future of RAG in AI and digital transformation.
Table of Contents
What is RAG?
Retrieval-Augmented Generation (RAG) is a technique that combines information retrieval with generative AI.
A traditional LLM generates responses mainly from patterns and knowledge acquired during training. A RAG-based application adds an additional step: it searches an external knowledge source for information relevant to the user’s question.
The retrieved information is then provided to the LLM as context. The model uses that context to generate its response.
Simple RAG Example
Imagine an employee asks:
“What is our company’s current leave policy?”
A general-purpose AI model may not know the company’s internal policy.
With RAG, the system can:
- Receive the employee’s question.
- Search the company’s policy documents.
- Find the relevant leave-policy section.
- Send that information to the LLM.
- Generate an answer based on the retrieved content.
Therefore, the AI does not need to have the company’s entire knowledge base memorized.
Why is RAG Important?
One of the biggest advantages of RAG is that it allows AI applications to work with information outside their original training data.
This is particularly valuable for organizations that need to use:
- Internal documents
- Product manuals
- Customer information
- Legal documents
- Technical documentation
- Knowledge bases
- Research papers
- Company policies
- Frequently updated databases
- Industry-specific information
RAG and AI Hallucinations
AI hallucination occurs when a model produces information that sounds convincing but is incorrect, unsupported, or fabricated.
RAG can help reduce this problem by giving the model relevant source material before generation.
However, it is important to understand that RAG does not guarantee that an AI system will never hallucinate. Poor retrieval, incorrect documents, weak prompts, or model limitations can still result in inaccurate answers.
The quality of the retrieved context is therefore critical.
How Does RAG Work?
A typical RAG system consists of two major pipelines:
- Ingestion Pipeline
- Retrieval and Generation Pipeline
The overall process can be represented as:
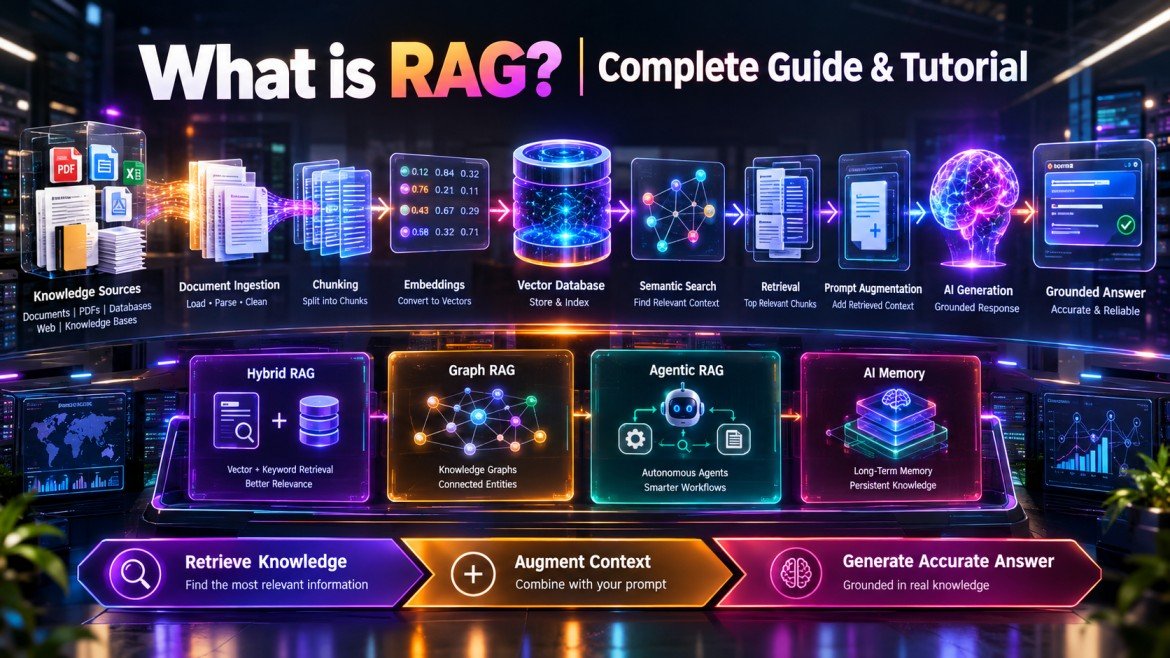
Documents → Chunking → Embeddings → Vector Database → User Query → Retrieval → Context → LLM → Answer
1. Ingestion Pipeline
The ingestion pipeline prepares external information so that an AI application can search it efficiently.
Step 1: Data Extraction
The system first collects information from different sources.
For example:
- PDF files
- Word documents
- Websites
- Databases
- CSV files
- Knowledge bases
- APIs
- Cloud storage
The information is converted into a format that the application can process.
Step 2: Document Chunking
Large documents are usually divided into smaller pieces called chunks.
For example, a 100-page employee handbook could be divided into sections such as:
- Leave policy
- Salary policy
- Working hours
- Travel policy
- Expense reimbursement
Chunking makes it easier to retrieve only the information relevant to a particular question.
Common Chunking Strategies
Fixed-Size Chunking
Text is divided according to a predefined number of characters or tokens.
Example:
Document
   ↓
500-token chunk
   ↓
500-token chunk
   ↓
500-token chunk
It is simple and predictable but may split related information across different chunks.
Semantic Chunking
The document is divided according to meaning rather than only size.
For example, an entire section describing a company’s reimbursement policy can remain together because its content is semantically related.
This can improve retrieval quality in some applications.
3. Creating Embeddings
After chunking, each chunk can be converted into a numerical representation called an embedding.
An embedding represents the semantic meaning of text as a vector.
For example:
"How can I claim travel expenses?"
             ↓
       Embedding Model
             ↓
[0.21, -0.43, 0.78, 0.15, ...]
The purpose is to allow the system to compare the meaning of different pieces of text mathematically.
4. Storing Data in a Vector Database
The generated embeddings are stored in a vector database or another vector-search system.
Popular technologies include:
- Pinecone
- ChromaDB
- Weaviate
- Milvus
- FAISS
- PostgreSQL with vector extensions
The database can store both the vector representation and useful metadata.
For example:
Document ID
Chunk ID
Text
Embedding
Department
Document Date
Access Permissions
Metadata becomes especially important in enterprise applications because retrieval can be restricted according to users, departments, dates, or document types.
The Retrieval Pipeline
Once the knowledge base has been prepared, users can interact with the AI system.
Suppose a user asks:
“What is the company’s work-from-home policy?”
The retrieval process begins.
Step 1: Convert the Query into an Embedding
The user’s question is converted into an embedding using an embedding model.
Step 2: Search for Relevant Information
The system searches the vector database for chunks that are semantically similar to the query.
Step 3: Select Relevant Context
The highest-relevance results are selected.
For example:
User Query
    ↓
Query Embedding
    ↓
Vector Search
    ↓
Top Relevant Chunks
    ↓
Context
Step 4: Augment the Prompt
The retrieved information is added to the prompt sent to the LLM.
Conceptually:
System Instructions
+
Retrieved Context
+
User Question
        ↓
       LLM
        ↓
Generated Answer
The result is a response grounded in the retrieved information.
RAG Architecture
A simplified RAG architecture looks like this:
             KNOWLEDGE SOURCES
                    |
       ---------------------------
       |      |       |          |
      PDF   Web     Database    API
       |      |       |          |
       -------- Data Processing -
                    |
                 Chunking
                    |
               Embeddings
                    |
             Vector Database
                    |
                    |
User Query → Query Embedding
                    |
              Similarity Search
                    |
             Relevant Context
                    |
             Prompt Augmentation
                    |
                   LLM
                    |
              Final Response
This architecture can be expanded with reranking, metadata filtering, security controls, agents, memory, evaluation systems, and external tools.
Important Technical Pillars of RAG
Building a reliable RAG application requires more than connecting an LLM to a vector database.
Several technical components strongly influence the final result.
1. Chunking Strategy
Poor chunking can reduce retrieval accuracy.
If chunks are too large, irrelevant information may be retrieved alongside useful information.
If chunks are too small, important context may be separated.
Developers may experiment with:
- Fixed-size chunks
- Overlapping chunks
- Sentence-based chunks
- Paragraph-based chunks
- Semantic chunks
- Document-structure-aware chunks
The optimal strategy depends on the type and structure of the source data.
2. Embedding Model
The embedding model converts text into vectors.
A good embedding model should represent semantic relationships effectively for the target language and domain.
For example, an insurance application may benefit from embeddings that perform well on specialized terminology.
Embedding selection should consider:
- Retrieval accuracy
- Language support
- Domain relevance
- Vector dimensions
- Latency
- Cost
- Infrastructure requirements
3. Vector Database
The vector database is responsible for efficiently storing and searching embeddings.
Technologies such as Pinecone and ChromaDB are commonly used in RAG prototypes and applications, while other vector-search solutions can be selected according to scalability, infrastructure, security, and integration requirements.
What is Hybrid RAG?
Traditional vector search is based primarily on semantic similarity.
However, semantic search is not always enough.
Consider a query containing an exact product ID:
“Find information about product AX-4729.”
An exact keyword match may be extremely valuable.
Hybrid RAG combines different retrieval methods, commonly:
- Keyword search
- Vector search
- Metadata filtering
- Reranking
This allows the system to benefit from both exact-term matching and semantic understanding.
RAG with Memory
A normal question-answering system may treat each query independently.
But conversational applications often need context.
For example:
User: What is RAG?
AI: RAG is a retrieval-based architecture for grounding LLM responses.
User: What are its main components?
The second question depends on the previous conversation.
A RAG system with memory can retain relevant conversational context and use it when processing subsequent requests.
This is particularly useful for:
- AI assistants
- Customer support
- Research assistants
- Enterprise chatbots
- Personal knowledge systems
Memory should nevertheless be carefully managed to prevent irrelevant or outdated context from affecting future answers.
What is Graph RAG?
Traditional retrieval often treats documents as collections of text chunks.
Graph RAG introduces relationships between entities and concepts.
For example, an organization’s data might contain relationships such as:
Customer
   ↓
Policy
   ↓
Claim
   ↓
Payment
   ↓
Repair Provider
A graph-based representation can help answer questions that depend on relationships across multiple pieces of information.
Graph-based approaches can be useful when the knowledge structure contains:
- Complex relationships
- Entities
- Dependencies
- Organizational structures
- Networks
- Connected events
What is Agentic RAG?
Agentic RAG extends the retrieval concept by allowing an AI agent to decide which tools or information sources it needs.
Instead of following one fixed retrieval process, an agent can potentially:
- Understand the question.
- Break it into subtasks.
- Select an appropriate tool.
- Search one or more knowledge sources.
- Analyze retrieved information.
- Perform calculations or external actions.
- Validate results.
- Generate a final response.
For example, an enterprise assistant could combine:
Internal documents + database query + API call + web search + calculator
to solve a complex business question.
This makes Agentic RAG particularly relevant to the future of AI-powered workflows.
What is Self-Reflective RAG?
Self-reflective RAG adds an evaluation or critique step.
Instead of generating an answer once and immediately returning it, the system can evaluate whether the retrieved evidence is sufficient and whether the generated response is supported.
A simplified workflow is:
Question
   ↓
Retrieve Information
   ↓
Generate Draft
   ↓
Evaluate Draft
   ↓
Need More Information?
   ↓
Retrieve Again / Revise
   ↓
Final Answer
This approach can improve reliability for complex questions, although it can also increase computational cost and latency.
RAG vs Fine-Tuning
RAG and fine-tuning solve different problems.
| Feature | RAG | Fine-Tuning |
|---|---|---|
| Uses external knowledge | Yes | Not directly |
| Easy to update knowledge | Generally yes | Requires additional training |
| Good for private documents | Yes | Possible, but requires training workflow |
| Useful for current information | Yes | Limited unless retrained |
| Changes model behavior/style | Limited | Stronger |
| Knowledge retrieval | Core capability | Not the primary purpose |
| Infrastructure complexity | Moderate | Can be higher |
A business does not necessarily have to choose only one approach. RAG and fine-tuning can also be combined when the application requires both external knowledge and specialized model behavior.
Real-World Applications of RAG
RAG has applications across many industries.
Customer Support
A support assistant can retrieve information from:
- Product documentation
- FAQs
- Troubleshooting guides
- Knowledge bases
- Support tickets
This allows responses to be grounded in the organization’s available information.
Healthcare and Research
Subject to appropriate privacy, security, and regulatory controls, RAG can help researchers search large collections of scientific or clinical documents.
Insurance
Insurance organizations can use retrieval-based AI applications to work with:
- Policy documents
- Claims procedures
- Underwriting guidelines
- Product documentation
- Regulatory information
For example, an internal assistant could retrieve relevant policy clauses before answering a claims-processing question.
Software Development
Developers can build assistants that retrieve:
- API documentation
- Coding standards
- Architecture documents
- Git repositories
- Technical specifications
This can help developers locate relevant technical information faster.
Legal and Compliance
Organizations can use retrieval systems to search large collections of:
- Contracts
- Regulations
- Policies
- Compliance documents
- Internal procedures
Such systems should provide appropriate citations and maintain strong access controls where required.
Benefits of RAG
A well-designed RAG architecture can provide several benefits.
1. More Grounded Responses
The model receives relevant external information before generating an answer.
2. Access to Private Knowledge
Organizations can connect AI applications to internal information without putting all proprietary knowledge into model training.
3. Easier Knowledge Updates
When the source documents change, the retrieval index can generally be updated without retraining the entire LLM.
4. Better Domain Relevance
The application can retrieve industry-specific information.
5. Potentially Lower Cost Than Retraining
For many knowledge-update scenarios, updating a retrieval system can be more practical than repeatedly retraining a model.
6. Improved Transparency
RAG applications can be designed to show the documents or passages that supported an answer.
Challenges of RAG
Despite its advantages, RAG is not a magic solution.
Retrieval Quality
If the correct document is not retrieved, even a powerful LLM may generate an incorrect response.
This is often described as:
Garbage in → garbage out.
Poor Chunking
Bad chunk boundaries can remove important context.
Context Window Limitations
Sending too many retrieved documents to an LLM can introduce irrelevant information and increase processing costs.
Outdated Knowledge Base
RAG can only retrieve what exists in its connected knowledge sources. If those sources are outdated, the generated response may also be outdated.
Security and Access Control
Enterprise systems must ensure that users cannot retrieve information they are not authorized to access.
Latency
Retrieval, reranking, external API calls, and generation can increase response time.
Evaluation Complexity
Evaluating a RAG system requires measuring both retrieval quality and answer quality.
How to Build a Simple RAG Application
A basic RAG tutorial can be understood through the following workflow.
Step 1: Collect Documents
Gather your PDFs, websites, text files, databases, or other trusted sources.
Step 2: Clean the Data
Remove unnecessary formatting, duplicate information, navigation elements, and irrelevant content.
Step 3: Split Documents
Divide the content into meaningful chunks.
Step 4: Generate Embeddings
Use an embedding model to convert each chunk into a vector representation.
Step 5: Store Embeddings
Save the vectors and associated metadata in a vector-search system.
Step 6: Process User Questions
Convert each user query into an embedding.
Step 7: Retrieve Relevant Chunks
Perform similarity search and optionally apply metadata filters or reranking.
Step 8: Create the Prompt
Combine the user’s question with the retrieved context.
Step 9: Generate the Answer
Send the augmented prompt to an LLM.
Step 10: Evaluate the Output
Check whether the answer is relevant, accurate, complete, and supported by the retrieved information.
Example RAG Workflow
Imagine a company has 10,000 internal documents.
An employee asks:
“What is the procedure for reporting a production software incident?”
A RAG application might perform the following:
Employee Question
        ↓
Query Embedding
        ↓
Search Knowledge Base
        ↓
Retrieve Incident Management Policy
        ↓
Retrieve Production Support Procedure
        ↓
Rerank Results
        ↓
Send Relevant Context to LLM
        ↓
Generate Grounded Response
The application can then provide the procedure and, where supported, references to the relevant internal documents.
How to Improve RAG Performance
Improving a RAG system requires looking beyond the LLM itself.
Improve Document Quality
Clean and structure source documents before indexing them.
Optimize Chunking
Test different chunk sizes, overlaps, and semantic strategies.
Improve Retrieval
Experiment with:
- Vector search
- Keyword search
- Hybrid search
- Metadata filtering
- Reranking
Use Domain-Appropriate Embeddings
Benchmark embedding models using real queries from your target application.
Add Source Citations
Showing supporting documents can improve transparency and make human verification easier.
Monitor the System
Track:
- Retrieval accuracy
- Answer accuracy
- Latency
- Failure rates
- User feedback
- Token usage
RAG Evaluation
A production RAG system should be evaluated systematically.
Important questions include:
Retrieval Evaluation
Did the system retrieve the correct information?
Generation Evaluation
Did the LLM produce an answer supported by the retrieved context?
Relevance
Does the response actually answer the user’s question?
Faithfulness
Is the answer consistent with the retrieved information?
Completeness
Did the response include the important information needed to answer the question?
Evaluation datasets should include realistic user questions and representative documents.
Future of RAG
The future of RAG is likely to involve increasingly intelligent retrieval and reasoning architectures.
Instead of simple “search and answer” systems, AI applications are moving toward systems that can dynamically decide what information they need and how to obtain it.
Important areas include:
Multimodal RAG
Future systems will increasingly retrieve information from:
- Text
- Images
- Audio
- Video
- Tables
- Charts
- PDFs
This can make knowledge retrieval more useful for complex enterprise content.
Agentic Retrieval
AI agents may dynamically select multiple tools and knowledge sources to solve complex problems.
Graph-Based Retrieval
Knowledge graphs and graph-oriented retrieval can become more important for applications where relationships between entities matter.
Real-Time RAG
Applications can retrieve information from frequently updated systems such as databases, APIs, operational systems, and enterprise platforms.
Personalized RAG
Systems can potentially tailor retrieval according to user roles, permissions, preferences, and conversation context while maintaining appropriate privacy controls.
RAG and Digital Transformation
The impact of RAG on digital transformation can be significant because it provides a practical way to connect generative AI with an organization’s existing knowledge.
Instead of replacing existing information systems, organizations can build an AI interface on top of them.
For example:
Existing Enterprise Data
          ↓
     RAG Layer
          ↓
       AI Assistant
          ↓
Employees / Customers / Teams
This approach can help organizations make large collections of existing information easier to access through natural-language interfaces.
RAG can therefore become an important component of enterprise AI strategies involving customer service, knowledge management, software development, research, operations, and decision-support workflows.
Opportunities for Businesses and Developers
The growth of RAG creates opportunities in several areas.
For Developers
Developers can build:
- Enterprise AI assistants
- Document chat applications
- Research tools
- Customer support systems
- Developer assistants
- Knowledge-management platforms
For Businesses
Organizations can explore AI applications for:
- Internal knowledge discovery
- Customer support
- Employee assistance
- Document analysis
- Compliance research
- Operational support
For AI Professionals
Knowledge of RAG increasingly involves multiple disciplines:
- LLMs
- Python
- APIs
- Vector databases
- Embeddings
- Information retrieval
- Prompt engineering
- Evaluation
- Data engineering
- AI security
RAG Best Practices
For a reliable production system, consider these practices:
- Use high-quality source data.
- Design chunks around the structure and meaning of documents.
- Select embedding models using real-world benchmarks.
- Combine semantic and keyword retrieval when appropriate.
- Apply metadata filtering.
- Use reranking for difficult retrieval tasks.
- Protect sensitive information with access controls.
- Monitor retrieval and generation separately.
- Provide citations where appropriate.
- Continuously evaluate performance.
- Keep the knowledge base synchronized with authoritative sources.
- Optimize latency and token consumption.
Conclusion
Retrieval-Augmented Generation (RAG) provides a practical architecture for connecting generative AI models with external knowledge.
Its core idea is straightforward: retrieve relevant information first, then use an LLM to generate an answer based on that information.
From basic document retrieval to Hybrid RAG, memory-enabled systems, Graph RAG, Agentic RAG, and self-reflective approaches, the technology is evolving rapidly.
The long-term future of RAG will likely involve multimodal retrieval, intelligent agents, real-time data access, graph-based knowledge, better evaluation, and stronger security.
For organizations undergoing digital transformation, RAG offers a way to make existing knowledge more accessible through natural-language AI interfaces. However, successful implementation requires more than simply connecting a vector database to an LLM. Data quality, retrieval accuracy, chunking, embeddings, security, evaluation, and system architecture all have a direct impact on the quality of the final application.
For developers and AI professionals, learning RAG provides a strong foundation for understanding how modern AI applications can move from general-purpose chatbots toward grounded, domain-specific, knowledge-aware systems.