
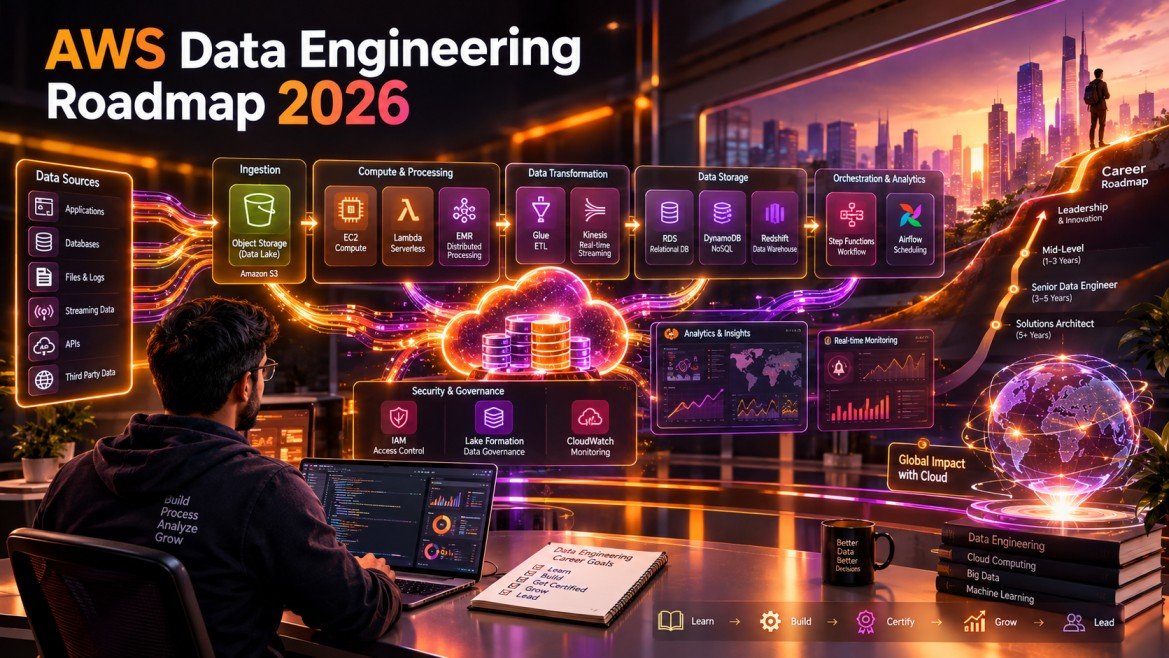
Data has become one of the most valuable assets for modern businesses. From fintech and healthcare to e-commerce and manufacturing, organizations increasingly depend on reliable data pipelines to make faster and smarter decisions.
This growing dependence has created strong demand for professionals who can collect, transform, store, secure, and analyze data in the cloud. Among the leading cloud ecosystems, Amazon Web Services (AWS) provides a broad collection of services for building modern data platforms.
The AWS Data Engineering career path combines programming, databases, cloud infrastructure, data processing, security, and workflow automation. If you are planning to enter this field in 2026, following a structured roadmap can help you avoid learning technologies randomly and instead build skills in the right sequence.
Table of Contents
What Is an AWS Data Engineer?
An AWS Data Engineer designs and maintains systems that move data from its source to a location where it can be analyzed and used.
Typical responsibilities include:
- Building data ingestion pipelines
- Designing data storage architectures
- Transforming raw data
- Developing ETL workflows
- Managing data lakes and warehouses
- Monitoring pipeline performance
- Implementing data security
- Automating data workflows
- Supporting analytics and business intelligence teams
For example, an e-commerce company may collect customer transactions, website activity, product information, and payment events. A data engineer can build pipelines that move this information into cloud storage and analytical platforms for business teams.
AWS Data Engineering Roadmap 2026
A practical learning sequence can be divided into several stages:
- Learn Python and SQL
- Understand data modeling
- Learn Git and Linux
- Build AWS fundamentals
- Master Amazon S3
- Understand databases and data warehouses
- Learn ETL and data processing
- Learn streaming data
- Master workflow orchestration
- Learn monitoring and security
- Build real-world projects
- Prepare for relevant AWS certifications
This progression provides a foundation before moving into advanced cloud data engineering.
Step 1: Master Python and SQL
Python
Python is one of the most useful programming languages for data engineers.
You should understand:
- Variables and data structures
- Functions
- Object-oriented programming basics
- File handling
- Exception handling
- APIs
- JSON and CSV processing
- Python environments
- Data-processing libraries
Python can be used to develop scripts, automate workflows, interact with APIs, validate data, and support ETL processes.
SQL
Strong SQL skills are essential because data engineers frequently work with structured datasets.
Learn:
- SELECT and filtering
- JOIN operations
- Aggregations
- Subqueries
- Common table expressions
- Window functions
- Views
- Indexing concepts
- Query optimization
A data engineer who knows cloud services but struggles with SQL will have difficulty working effectively with analytical data.
Step 2: Learn Data Modeling
Data modeling explains how information should be organized.
Start with Entity-Relationship Diagrams (ERDs) and understand how entities, attributes, and relationships connect.
Normalization
Normalization helps reduce unnecessary duplication and improve data consistency.
Denormalization
Denormalization intentionally combines information to improve query performance or simplify analytical workloads.
Understanding when to normalize and when to denormalize is an important data-engineering skill.
Step 3: Learn Git and Linux
Git
Git provides version control for code and configuration.
Learn how to:
- Create repositories
- Commit changes
- Create branches
- Merge code
- Resolve conflicts
- Work with remote repositories
- Review changes
Linux
Basic Linux knowledge is also valuable when working with cloud environments.
Become comfortable with:
- File and directory commands
- Permissions
- Environment variables
- Processes
- Shell commands
- Package management
- Basic Bash scripting
These skills become particularly useful when troubleshooting cloud infrastructure and automated pipelines.
Step 4: Understand Core AWS Services
After developing foundational skills, begin learning AWS.
Amazon S3
Amazon Simple Storage Service (S3) is one of the most important services in the AWS Data Engineering ecosystem.
It can be used for:
- Raw data storage
- Data lakes
- Processed datasets
- Backup files
- Logs
- Analytical datasets
A typical data lake might organize information into folders such as:
/raw
/processed
/curated
/archive
Understanding storage classes, lifecycle policies, permissions, partitioning, and object organization is important.
Amazon EC2
Amazon EC2 provides virtual computing capacity.
Data engineers may use EC2 when they need more control over the underlying computing environment.
AWS Lambda
Lambda provides serverless execution for event-driven workloads.
For example, uploading a file to S3 could trigger a Lambda function that validates the file or initiates another workflow.
Step 5: Learn AWS Databases
Different workloads require different database technologies.
Amazon RDS
Amazon RDS supports relational database engines and is useful for traditional structured workloads.
Amazon DynamoDB
DynamoDB is a managed NoSQL database designed for applications requiring scalable, low-latency access.
Amazon Redshift
Amazon Redshift is designed for large-scale analytical workloads and data warehousing.
A practical roadmap should teach you not only what each service does, but also why you would choose one over another.
Step 6: Learn ETL and Data Processing
ETL stands for Extract, Transform, and Load.
A typical pipeline might:
Extract → Transform → Validate → Load → Monitor
AWS Glue
AWS Glue provides managed, serverless capabilities for data integration and ETL.
It can help discover, transform, and prepare datasets for analytics.
Amazon EMR
Amazon EMR is useful for large-scale distributed data processing and supports technologies such as Apache Spark.
Learn EMR when you need to understand distributed processing and large datasets.
Amazon Kinesis
Kinesis is important when applications need to process streaming information.
Examples include:
- Website events
- Application logs
- IoT data
- Financial transactions
- Real-time user activity
Understanding both batch and streaming architectures will make your skill set more versatile.
Step 7: Master Workflow Orchestration
A production data pipeline usually involves multiple dependent tasks.
For example:
Ingest → Validate → Transform → Load → Quality Check → Notify
AWS Step Functions
Step Functions can coordinate AWS services and create workflows using visual and state-based orchestration.
It can be useful for relatively straightforward workflows.
Amazon MWAA
Managed Workflows for Apache Airflow (MWAA) provides a managed environment for Apache Airflow.
Airflow is particularly useful for code-defined workflows involving multiple tasks and dependencies.
Understanding when to use Step Functions versus Airflow is more valuable than memorizing either tool independently.
Step 8: Learn Monitoring and Security
Production pipelines must be reliable and secure.
Amazon CloudWatch
CloudWatch can help monitor:
- Logs
- Metrics
- Alarms
- Application activity
- Infrastructure behavior
Monitoring helps engineers identify failures before they become major business problems.
AWS IAM
Identity and Access Management (IAM) is essential for controlling who or what can access AWS resources.
Learn:
- Users
- Roles
- Policies
- Permissions
- Least-privilege access
Security should be incorporated into the architecture from the beginning rather than added after deployment.
AWS Lake Formation
Lake Formation provides capabilities for managing and governing data lakes.
It becomes particularly relevant when organizations need controlled access to large collections of analytical data.
Building Real-World AWS Data Engineering Projects
Learning services individually is not enough. Practical projects demonstrate that you can connect them into complete solutions.
Project 1: Batch Data Pipeline
Build a pipeline that:
- Receives CSV files
- Stores them in S3
- Catalogs the data
- Transforms it using Glue
- Loads analytical data into Redshift
- Monitors execution through CloudWatch
Project 2: Real-Time Pipeline
Create a streaming architecture using:
- Kinesis
- Lambda
- S3
- Analytical storage
- CloudWatch
The project can simulate website events or IoT sensor data.
Project 3: Automated Data Workflow
Create a multi-step pipeline using Step Functions or Airflow.
Include:
- Data validation
- Transformation
- Error handling
- Retry logic
- Notifications
- Logging
These projects can become valuable portfolio pieces when applying for data engineering positions.
AWS Certifications for Data Engineers
Certifications can validate your understanding of AWS technologies.
AWS Certified Data Engineer – Associate
The AWS Certified Data Engineer – Associate is particularly relevant for professionals developing skills in data ingestion, transformation, storage, monitoring, and data security.
AWS Certified Data Analytics – Specialty
For experienced professionals, the Data Analytics – Specialty certification can provide deeper validation of AWS analytics knowledge.
Certification should complement hands-on experience rather than replace it.
Challenges in AWS Data Engineering
The field offers strong opportunities, but becoming proficient requires overcoming several challenges.
Large Technology Landscape
AWS contains hundreds of services. Beginners can easily become overwhelmed.
Solution: Focus first on services directly related to data engineering instead of trying to learn AWS as a whole.
Cost Management
Cloud resources can generate unexpected expenses.
Solution: Learn budgeting, resource monitoring, lifecycle policies, and cost-aware architecture.
Data Quality
Incorrect, incomplete, duplicated, or inconsistent data can damage downstream analytics.
Solution: Include validation and quality checks within the pipeline.
Security Complexity
Cloud data environments require careful management of permissions and sensitive information.
Solution: Learn IAM, encryption, access controls, auditing, and least-privilege principles.
Pipeline Reliability
A pipeline that works once is not necessarily production-ready.
Engineers must consider:
- Retries
- Failure handling
- Monitoring
- Idempotency
- Data validation
- Recovery procedures
Future Trends in AWS Data Engineering
The future of technology will significantly influence the data engineering profession.
AI-Assisted Data Engineering
Generative AI can assist engineers with:
- SQL generation
- Code creation
- Documentation
- Pipeline troubleshooting
- Data-quality analysis
- Infrastructure configuration
Human expertise will remain important for architecture, validation, security, and business decisions.
Serverless Data Platforms
Organizations are increasingly interested in reducing infrastructure management. Serverless architectures can allow teams to focus more on data workflows and less on maintaining servers.
Real-Time Analytics
Businesses increasingly want decisions based on current information rather than yesterday’s reports.
This will increase the importance of streaming technologies and event-driven architectures.
Data Governance
As organizations collect more data, governance, privacy, lineage, and access control will become increasingly important.
Data and AI Convergence
AI applications require high-quality, accessible data. This creates a closer relationship between data engineering, machine learning, analytics, and AI engineering.
Career Opportunities
The AWS Data Engineering skill set can lead to multiple career paths.
Potential roles include:
- AWS Data Engineer
- Cloud Data Engineer
- Data Architect
- Analytics Engineer
- Big Data Engineer
- Data Platform Engineer
- Cloud Architect
- Data Engineering Consultant
Professionals can work across industries such as:
- Banking and fintech
- Healthcare
- Insurance
- Retail
- Manufacturing
- Telecommunications
- E-commerce
- Technology
The digital transformation of traditional businesses is also increasing the need for professionals who can modernize legacy data platforms and build scalable cloud architectures.
AWS Data Engineering Roadmap: Final Checklist
Before applying for your first role, aim to become comfortable with:
- Python
- SQL
- Data modeling
- Git
- Linux
- Amazon S3
- EC2
- Lambda
- RDS
- DynamoDB
- Redshift
- AWS Glue
- Kinesis
- EMR
- Step Functions
- MWAA
- CloudWatch
- IAM
- Lake Formation
- Data security
- ETL architecture
- Batch processing
- Streaming pipelines
- Data quality
- Cloud cost management
Conclusion
The AWS Data Engineering career path in 2026 offers a structured way to combine programming, databases, cloud computing, data processing, security, and analytics.
The most effective approach is to learn progressively. Start with Python, SQL, data modeling, Git, and Linux. Then move into S3, databases, ETL, streaming, orchestration, monitoring, and security. Finally, reinforce your knowledge through practical projects and relevant certification.
The impact of digital transformation will continue to increase demand for reliable cloud-based data platforms. At the same time, AI is changing how engineers develop, monitor, and optimize data systems.
Professionals who combine strong fundamentals with AWS expertise, practical problem-solving, and an understanding of the future of technology can position themselves for a wide range of opportunities in the evolving data economy.